Best local LLMs for Mac Studio M5 Ultra 256GB

Mac Studio M5 Ultra 256GB has 256GB of unified memory and is a strong fit for very large quantized local models. These recommendations are generated from the current LocalClaw catalogue and filtered for realistic memory headroom.

Pre-order now · Available September 22, 2026 · Specifications verified on Apple.com

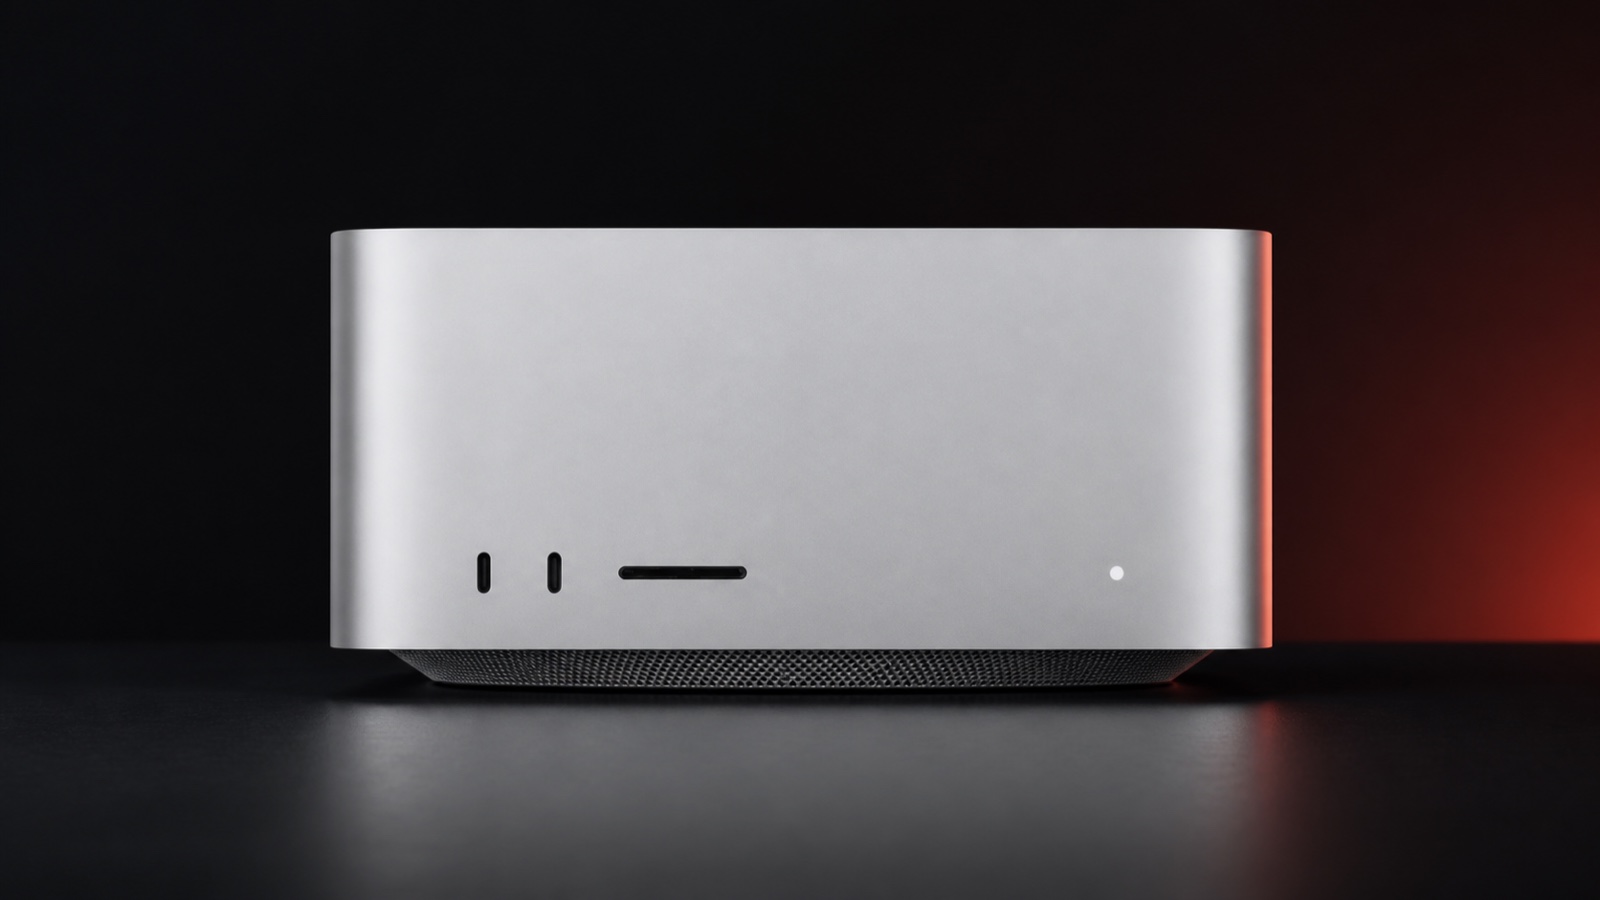
Silver Mac Studio in a dark studio setting
Mac Studio · M5 Ultra · 256GB unified memory
Chip
M5 Ultra
Unified memory
256GB
Compatible catalogue models
220
Best match
DeepSeek V4 Flash Vision Exp

Can Mac Studio M5 Ultra 256GB run local AI?

Yes. With 256GB of unified memory, Mac Studio M5 Ultra 256GB fits 220 current LocalClaw catalogue models under the conservative 8k-context memory filter. Start with DeepSeek V4 Flash Vision Exp. Apple lists it for pre-order, with availability beginning September 22, 2026. This is memory-fit guidance, not a hands-on speed benchmark.

Direct answer · Verified August 25, 2026

Apple-confirmed specifications used here

CPUUp to 36-core
GPUUp to 80-core
Neural Engine32-core
Unified memory256GB
Family maximum512GB
Memory bandwidth1.2TB/s

Hardware facts come from Apple. LocalClaw separately calculates catalogue compatibility from unified memory and model requirements. No unreleased Mac performance result is inferred from chip specifications.

Primary sources checked August 25, 2026 · Dataset license and reuse conditions

Mac Studio M5 Ultra 256GB local AI FAQ

Can Mac Studio M5 Ultra 256GB run local AI models?

Yes. With 256GB of unified memory, Mac Studio M5 Ultra 256GB fits 220 current LocalClaw catalogue models under the conservative 8k-context memory filter. Start with DeepSeek V4 Flash Vision Exp. Apple lists it for pre-order, with availability beginning September 22, 2026. This is memory-fit guidance, not a hands-on speed benchmark.

How much unified memory does Mac Studio M5 Ultra 256GB have?

This configuration has 256GB of unified memory. Apple lists up to 512GB for the M5 Ultra family represented here. LocalClaw reserves memory for macOS, the runtime and an 8k context before marking a model compatible.

Is Mac Studio M5 Ultra 256GB available now?

It is available to pre-order from Apple. Apple says availability begins September 22, 2026.

Are these Mac Studio M5 Ultra 256GB benchmark results?

No. The compatibility count and ranking are calculated from 256GB of unified memory and the current LocalClaw catalogue. They are not measured tokens-per-second results or hands-on benchmarks.

Best local AI starting point for Mac Studio M5 Ultra 256GB

Start with DeepSeek V4 Flash Vision Exp on this Mac. This Mac is not shipping yet, so LocalClaw has not hands-on validated runtime speed. Model fit is calculated conservatively from Apple-confirmed unified memory. A tight fit can still work, but close other apps, reduce context length when needed, and prefer the listed quantization.

Mac Studio · M5 Ultra · 256GB unified memory · 2TB SSD · Pre-order · Sep 22

Top compatible local LLMs

#1Best match

DeepSeek V4 Flash Vision Exp

Official MIT DeepSeek V4 Flash multimodal experiment with image understanding, 1M context and Unsloth Dynamic GGUF artifacts. The lightest practical GGUF is roughly 82-97GB, while higher-quality Q4/Q8 builds are about 155-162GB, so this belongs on large-memory workstations.

Parameters284B (13B active, multimodal MoE)Minimum RAM128GBQuantizationUD-Q2_K_XLModel size97GB
View model details →
#2Best match

Xing4.0-29B-A4B

Official China Telecom XingChen-AGI Apache 2.0 MoE release with 29B total parameters, 4B active parameters, 256K native context and an official IQ4_NL GGUF path for llama.cpp-class local inference on 24GB GPU workstations.

Parameters29B (4B active, MoE)Minimum RAM32GBQuantizationIQ4_NL GGUFModel size20.1GB
View model details →
#3Best match

Occamy-1.0

Accio Lab Apache 2.0 co-work model post-trained from Qwen3.6-35B-A3B for long-horizon tools, files, code and business workflows. Official GGUF Q4_K_M is 19.7GiB with llama.cpp validation evidence.

Parameters35B (3B active, MoE)Minimum RAM32GBQuantizationQ4_K_MModel size19.7GB
View model details →
#4Best match

Nex-N2.5-mini

Official Nex-AGI Apache 2.0 multimodal agent model for computer use, web browsing, coding and tool calling. Community Q4_K_M GGUF is about 21.3GB with documented llama.cpp text and vision smoke tests.

Parameters35B MoEMinimum RAM32GBQuantizationQ4_K_MModel size21.3GB
View model details →
#5Best match

Qwen3.8 Flash Next

Official Qwen sparse multimodal MoE preview with 125B model parameters plus 51B n-gram embeddings, about 6B active parameters, Qwen Community 1.0 licensing, 262K native context and local Q4_K_M GGUF paths for llama.cpp, Ollama and LM Studio-class runtimes.

Parameters125B + 51B n-gram (6B active)Minimum RAM96GBQuantizationQ4_K_MModel size54.5GB
View model details →
#6Best match

Ornith-1.5-35B-A3B

Official MIT 35B MoE reasoning model from Ornith AI with about 3B active parameters, 262K context, strong agentic-coding positioning and official Q4_K_M GGUF plus MLX/Ollama/llama.cpp local paths for larger workstations.

Parameters35B (3B active, MoE)Minimum RAM48GBQuantizationQ4_K_MModel size21.72GB
View model details →
#7Best match

Muse Glimmer 30B

Meta Superintelligence Lab local agent model with text+image input, 131K context, Apache 2.0 weights and official GGUF/ExecuTorch artifacts. The K-Quant 17GB build targets 24GB machines; 32GB is safer for vision and long-context sessions.

Parameters29.8B multimodalMinimum RAM24GBQuantizationK-Quant 17GB Q4_K_MModel size17GB
View model details →
#8Best match

Qwen3.8-27B

Official Qwen dense 27B vision-language release with Apache 2.0 weights, 262K native context, thinking controls and strong agentic coding benchmarks. Practical local path through Unsloth and LM Studio-compatible GGUF artifacts.

Parameters27BMinimum RAM32GBQuantizationQ4_K_MModel size16.8GB
View model details →
#9Best match

Granite 4.2 (30B)

IBM Granite 4.2 30B brings the permissive Apache 2.0 Granite stack to workstation-class local reasoning, RAG, coding and tool-use workflows with GGUF and MLX community artifacts.

Parameters29.3BMinimum RAM32GBQuantizationQ4_K_MModel size18GB
View model details →
How this order works

The shared LocalClaw engine first rejects hosted-only, excluded and oversized records. It reserves system and 8k-context headroom, labels comfortable, good and tight fits, then ranks the remaining models by hardware fit, use case, catalogue capability ratings, runtime and freshness. Community stars are never included. This is practical guidance, not a standardized third-party benchmark.

Browse the full model index

Buying note

This guide is about local AI fit, not live pricing. Prices and availability change. This Mac can be pre-ordered from Apple and is scheduled to become available September 22, 2026.